Sergey Tulyakov

Sergey Tulyakov

Co-founder & Co-CEO, Dotmo

I’ve worked on video generation since before it worked, starting with MoCoGAN in 2017. At Snap I founded the Creative Vision research team and grew it to more than 20 people, hosting about 30 interns a year. Together we became one of the most prolific research teams in generative AI, spanning video, images, 3D and 4D. Along the way we developed four generations of the Snap Video model family and the on-device image models SnapFusion and SnapGen. Our work went into Snapchat’s AI video clips and its ML, 3D and 4D Lenses, along with much of the technology behind Snap’s most engaging products, which reach hundreds of millions of people every day.

Now the core of that team is building Dotmo, and we’re hiring researchers, engineers and designers.

What we’re building

At Dotmo we’re building a new platform for games and social experiences. At its core is a foundational layer of playable models: generative models you play, not just watch or steer a camera through. Everything on the platform, from 3D worlds to 2D games and puzzles, is generated live, follows real rules, reacts to what each player does, and can be shared by many players at once.

The idea goes back to 2021, when we introduced playable video generation and showed that game-like controls can be learned automatically from unlabeled videos.

Products and press

Since 2018, we have invented and kept improving the core technology behind Snapchat’s Gen AI Lenses, from the first real-time generative networks on the phone to fast, scalable Lenses generated on the server. Many teams built the Lenses themselves on top of our technology. Snap co-founder Bobby Murphy said that “our popular gender and age transformation lenses, our anime lens, our cartoon lens… have become incredible viral hits”.

200M+
people played with Gender Swap and Baby in their first two weeks
7–9M
of the 13M daily users Snap added that quarter, which its CFO tied to these Lenses
6.8B+
first-week plays and views of Anime Style, Cartoon and Cartoon 3D Style
400M+
people used Gen AI Lenses more than 4 billion times in Q4 2024
Real-time on mobile
Face LensesGenerative face transforms2019
Real-Time GenAISnapFusion restyling the live camera2024
Selfie AttachmentsGenerated 3D and 4D attachments2025
On the server
AI LensesImages generated from a selfie2023
AI Video LensesVideos generated from a selfie2025
AI Video TransformYour recorded video, edited with a prompt2026
Sep 2026
AI Video Transform, built on the video model we developed, edits your own recordings with a text prompt · Lens Studio · Easy Lens
Mar 2025
AI Video Lenses in Snapchat, powered by our video model · Snap Newsroom
Feb 2025
Our on-device text-to-image model, for AI Snaps and AI Bitmoji Backgrounds · Snap Newsroom
Sep 2024
AI video generation for Snapchat creators, powered by our video models, which TechCrunch noted put Snap ahead of TikTok and Instagram · TechCrunch
Jun 2024
Snap co-founder Bobby Murphy previews our real-time, on-device image model at AWE 2024 · YouTube · TechCrunch
Jun 2023
SnapFusion, our text-to-image model that runs on a phone in under two seconds · Snap Newsroom
Jul 2021
Magic Karaoke Lens, which animates any face, even one in a photo, to sing along to a song · Next Reality
Sep 2020
Two Minute Papers explains the real-time video style transfer we developed with CTU Prague · YouTube
May 2020
Lil Uzi Vert’s “Wassup” video with Future, whose animated celebrity portraits were built on top of our First Order Motion Model, credited in the video’s description · YouTube
Mar 2020
Two Minute Papers explains our First Order Motion Model in an episode with over a million views · YouTube
Nov 2019
Time Machine Lens, which makes your face younger or older in real time · Engadget
May 2019
Gender Swap and Baby Lenses. Snap reported that “over 200 million Snapchatters played with these new Lenses in the first two weeks” · Snap, Q2 2019 results · Social Media Today

Research

I’ve published more than 100 papers at top venues including CVPR, NeurIPS, ICLR, ICML, ICCV, ECCV, SIGGRAPH, TPAMI and IJCV, and hold more than 50 granted US patents, with dozens more pending.

Selected papers
MoCoGAN
MoCoGAN
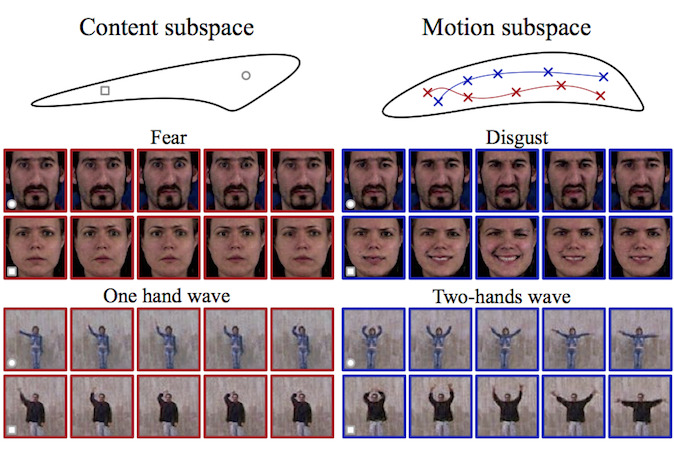
Generates video by separating motion from content, so either can change while the other stays fixed.
CVPR 2018CodePaper
First Order Motion Model
Animates a still image from a driving video, with no labels or pre-trained keypoint detectors.
NeurIPS 2019ProjectPaper
Playable Video Generation
Lets you control a generated video the way you play a video game, choosing an action at each step.
CVPR 2021OralProjectPaper
4Real-Video
Generates a moving scene from many camera angles at once, as one grid of frames across time and viewpoint.
CVPR 2025HighlightProjectPaper
Snap Video
A video-first transformer, 3.3× faster to train than U-Nets, that scaled text-to-video to billions of parameters.
CVPR 2024HighlightProjectPaper
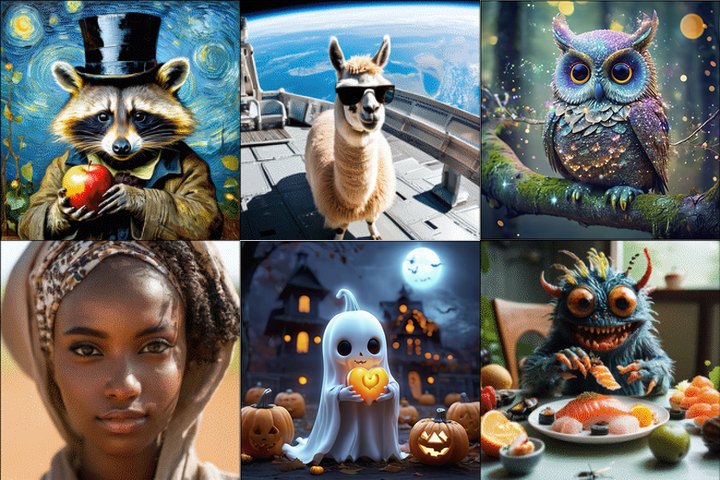
SnapGen
SnapGen
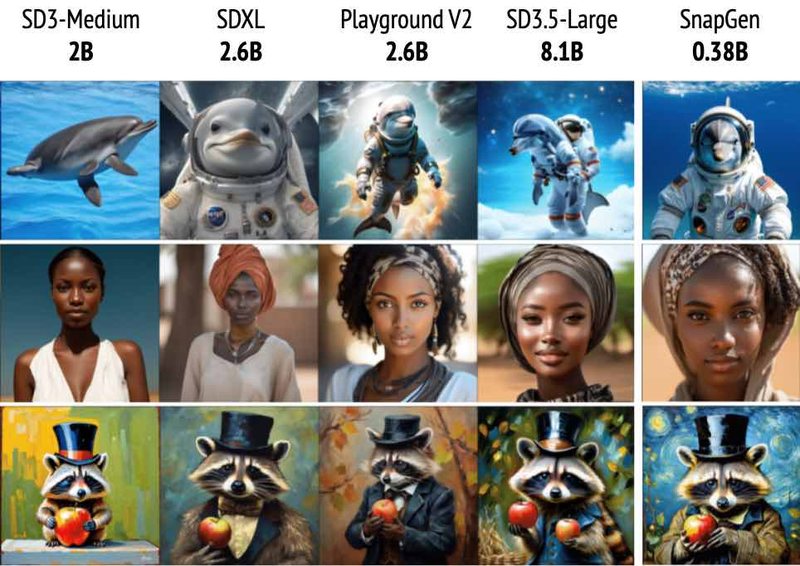
The first 1024 px text-to-image model on a phone, in about 1.4 s, outperforming SD3-Medium in human evaluation at a fifth of its size.
CVPR 2025HighlightProjectPaper

Recognition

2024 – 2026
Associate Editor, IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)
Since 2022
Area Chair, CVPR · ECCV · ICCV · NeurIPS · ICLR · ICML · WACV · 3DV
2020
Best in Show, SIGGRAPH Real-Time Live! — Interactive Style Transfer to Live Video Streams · ACM SIGGRAPH
Since 2020
Keynotes at CVPR, ICCV, ECCV, NeurIPS and SIGGRAPH workshops. Tutorials at CVPR 2021, ECCV 2022 and CVPR 2023. Invited lectures at Stanford, UC Berkeley, CMU, Caltech, USC, UCLA and UC Merced

Experience

DotmoJun 2026 – Present
Culver City, CA
Co-founder & Co-CEO
Snap Inc.Jul 2017 – Jun 2026
Santa Monica, CA
Director of ResearchJul 2024 – Jun 2026
Principal Research Scientist, Senior ManagerMar 2022 – Jul 2024
Principal Research Scientist, ManagerMar 2021 – Mar 2022
Lead Research ScientistDec 2018 – Mar 2021
Senior Research ScientistJul 2017 – Dec 2018

Education

University of Trento2012 – 2017
PhD · Trento, Italy
Carnegie Mellon UniversitySep 2014 – Feb 2015
Visiting PhD student · Robotics Institute
Belarusian State University of Informatics and Radioelectronics2004 – 2010
MSc & BEng · Diploma with Highest Distinction

Publications

Selected works. 17,000+ citations, h-index 56. Full record on Google Scholar.

Video Generation & Animation
Snap Video: Scaled Spatiotemporal Transformers for Text-to-Video Synthesis
Willi Menapace, Aliaksandr Siarohin, Ivan Skorokhodov, Ekaterina Deyneka, Tsai-Shien Chen, Anil Kag, Yuwei Fang, Aleksei Stoliar, Elisa Ricci, Jian Ren, Sergey Tulyakov
CVPR 2024HighlightProjectPaper
Panda-70M: Captioning 70M Videos with Multiple Cross-Modality Teachers
Tsai-Shien Chen, Aliaksandr Siarohin, Willi Menapace, Ekaterina Deyneka, Hsiang-wei Chao, Byung Eun Jeon, Yuwei Fang, Hsin-Ying Lee, Jian Ren, Ming-Hsuan Yang, Sergey Tulyakov
CVPR 2024ProjectPaper
Motion Representations for Articulated Animation
Aliaksandr Siarohin, Oliver J. Woodford, Jian Ren, Menglei Chai, Sergey Tulyakov
CVPR 2021ProjectPaper
A Good Image Generator Is What You Need for High-Resolution Video Synthesis
Yu Tian, Jian Ren, Menglei Chai, Kyle Olszewski, Xi Peng, Dimitris N. Metaxas, Sergey Tulyakov
ICLR 2021SpotlightProjectPaper
First Order Motion Model for Image Animation
Aliaksandr Siarohin, Stéphane Lathuilière, Sergey Tulyakov, Elisa Ricci, Nicu Sebe
NeurIPS 2019ProjectPaper
Animating Arbitrary Objects via Deep Motion Transfer
Aliaksandr Siarohin, Stéphane Lathuilière, Sergey Tulyakov, Elisa Ricci, Nicu Sebe
CVPR 2019OralCodePaper
MoCoGAN
MoCoGAN: Decomposing Motion and Content for Video Generation
Sergey Tulyakov, Ming-Yu Liu, Xiaodong Yang, Jan Kautz
CVPR 2018CodePaper
Playable Video & Games
Promptable Game Models: Text-Guided Game Simulation via Masked Diffusion Models
Willi Menapace, Aliaksandr Siarohin, Stéphane Lathuilière, Panos Achlioptas, Vladislav Golyanik, Sergey Tulyakov, Elisa Ricci
ACM TOG 2024ProjectPaper
Playable Environments: Video Manipulation in Space and Time
Willi Menapace, Stéphane Lathuilière, Aliaksandr Siarohin, Christian Theobalt, Sergey Tulyakov, Vladislav Golyanik, Elisa Ricci
CVPR 2022ProjectPaper
Playable Video Generation
Willi Menapace, Stéphane Lathuilière, Sergey Tulyakov, Aliaksandr Siarohin, Elisa Ricci
CVPR 2021OralProjectPaper
Personalization & Control
Nested Attention
Nested Attention: Semantic-aware Attention Values for Concept Personalization
Or Patashnik, Rinon Gal, Daniil Ostashev, Sergey Tulyakov, Kfir Aberman, Daniel Cohen-Or
SIGGRAPH 2025ProjectPaper
Dynamic Concepts Personalization from Single Videos
Rameen Abdal, Or Patashnik, Ivan Skorokhodov, Willi Menapace, Aliaksandr Siarohin, Sergey Tulyakov, Daniel Cohen-Or, Kfir Aberman
SIGGRAPH 2025ProjectPaper
AC3D: Analyzing and Improving 3D Camera Control in Video Diffusion Transformers
Sherwin Bahmani, Ivan Skorokhodov, Guocheng Qian, Aliaksandr Siarohin, Willi Menapace, Andrea Tagliasacchi, David B. Lindell, Sergey Tulyakov
CVPR 2025ProjectPaper
Mind the Time: Temporally-Controlled Multi-Event Video Generation
Ziyi Wu, Aliaksandr Siarohin, Willi Menapace, Ivan Skorokhodov, Yuwei Fang, Varnith Chordia, Igor Gilitschenski, Sergey Tulyakov
CVPR 2025ProjectPaper
Multi-subject Open-set Personalization in Video Generation
Tsai-Shien Chen, Aliaksandr Siarohin, Willi Menapace, Yuwei Fang, Kwot Sin Lee, Ivan Skorokhodov, Kfir Aberman, Jun-Yan Zhu, Ming-Hsuan Yang, Sergey Tulyakov
CVPR 2025ProjectPaper
MoA
MoA: Mixture-of-Attention for Subject-Context Disentanglement in Personalized Image Generation
Kuan-Chieh Wang, Daniil Ostashev, Yuwei Fang, Sergey Tulyakov, Kfir Aberman
SIGGRAPH Asia 2024ProjectPaper
3D / 4D
4Real-Video: Learning Generalizable Photo-Realistic 4D Video Diffusion
Chaoyang Wang, Peiye Zhuang, Tuan Duc Ngo, Willi Menapace, Aliaksandr Siarohin, Michael Vasilkovsky, Ivan Skorokhodov, Sergey Tulyakov, Peter Wonka, Hsin-Ying Lee
CVPR 2025HighlightProjectPaper
DELTA: Dense Efficient Long-range 3D Tracking for Any Video
Tuan Duc Ngo, Peiye Zhuang, Chuang Gan, Evangelos Kalogerakis, Sergey Tulyakov, Hsin-Ying Lee, Chaoyang Wang
ICLR 2025ProjectPaper
4Real: Towards Photorealistic 4D Scene Generation via Video Diffusion Models
Heng Yu, Chaoyang Wang, Peiye Zhuang, Willi Menapace, Aliaksandr Siarohin, Junli Cao, Laszlo A. Jeni, Sergey Tulyakov, Hsin-Ying Lee
NeurIPS 2024ProjectPaper
TC4D: Trajectory-Conditioned Text-to-4D Generation
Sherwin Bahmani, Xian Liu, Wang Yifan, Ivan Skorokhodov, Victor Rong, Ziwei Liu, Xihui Liu, Jeong Joon Park, Sergey Tulyakov, Gordon Wetzstein, Andrea Tagliasacchi, David B. Lindell
ECCV 2024ProjectPaper
Magic123: One Image to High-Quality 3D Object Generation Using Both 2D and 3D Diffusion Priors
Guocheng Qian, Jinjie Mai, Abdullah Hamdi, Jian Ren, Aliaksandr Siarohin, Bing Li, Hsin-Ying Lee, Ivan Skorokhodov, Peter Wonka, Sergey Tulyakov, Bernard Ghanem
ICLR 2024ProjectPaper
SDFusion: Multimodal 3D Shape Completion, Reconstruction, and Generation
Yen-Chi Cheng, Hsin-Ying Lee, Sergey Tulyakov, Alexander Schwing, Liangyan Gui
CVPR 2023ProjectPaper
Unsupervised Volumetric Animation
Aliaksandr Siarohin, Willi Menapace, Ivan Skorokhodov, Kyle Olszewski, Jian Ren, Hsin-Ying Lee, Menglei Chai, Sergey Tulyakov
CVPR 2023ProjectPaper
3D Generation on ImageNet
Ivan Skorokhodov, Aliaksandr Siarohin, Yinghao Xu, Jian Ren, Hsin-Ying Lee, Peter Wonka, Sergey Tulyakov
ICLR 2023OralProjectPaper
Efficient AI
SnapGen
SnapGen: Taming High-Resolution Text-to-Image Models for Mobile Devices with Efficient Architectures and Training
Dongting Hu, Jierun Chen, Xijie Huang, Huseyin Coskun, Arpit Sahni, Aarush Gupta, Anujraaj Goyal, Dishani Lahiri, Rajesh Singh, Yerlan Idelbayev, Junli Cao, Yanyu Li, Kwang-Ting Cheng, S.-H. Gary Chan, Mingming Gong, Sergey Tulyakov, Anil Kag, Yanwu Xu, Jian Ren
CVPR 2025HighlightProjectPaper
SnapGen-V: Generating a Five-Second Video within Five Seconds on a Mobile Device
Yushu Wu, Zhixing Zhang, Yanyu Li, Yanwu Xu, Anil Kag, Yang Sui, Huseyin Coskun, Ke Ma, Aleksei Lebedev, Ju Hu, Dimitris Metaxas, Yanzhi Wang, Sergey Tulyakov, Jian Ren
CVPR 2025ProjectPaper
BitsFusion
BitsFusion: 1.99 bits Weight Quantization of Diffusion Model
Yang Sui, Yanyu Li, Anil Kag, Yerlan Idelbayev, Junli Cao, Ju Hu, Dhritiman Sagar, Bo Yuan, Sergey Tulyakov, Jian Ren
NeurIPS 2024ProjectPaper
SnapFusion
SnapFusion: Text-to-Image Diffusion Model on Mobile Devices within Two Seconds
Yanyu Li, Huan Wang, Qing Jin, Ju Hu, Pavlo Chemerys, Yun Fu, Yanzhi Wang, Sergey Tulyakov, Jian Ren
NeurIPS 2023ProjectPaper
Rethinking Vision Transformers for MobileNet Size and Speed
Yanyu Li, Ju Hu, Yang Wen, Georgios Evangelidis, Kamyar Salahi, Yanzhi Wang, Sergey Tulyakov, Jian Ren
ICCV 2023CodePaper
EfficientFormer
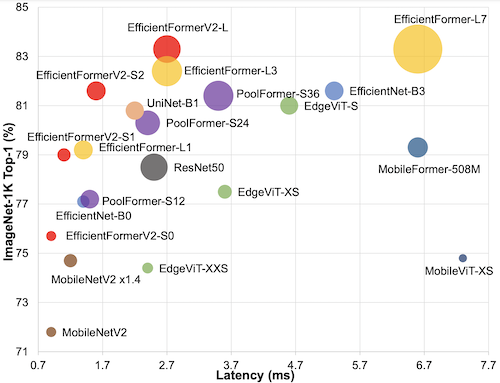
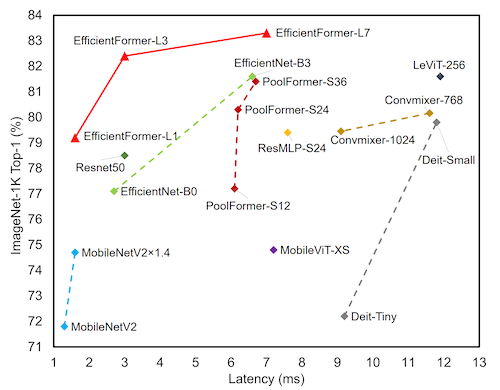
EfficientFormer: Vision Transformers at MobileNet Speed
Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren
NeurIPS 2022CodePaper